MOSS-Live system shows high performance in voice metrics but lags behind GPT-Live-1 in multi-turn tasks
Read more
Pandaily
pandaily.com

MOSS-Live system shows high performance in voice metrics but lags behind GPT-Live-1 in multi-turn tasks

The OpenMOSS team from Fudan University and MOSI Intelligence presented a detailed evaluation of their full-duplex voice interaction system, MOSS-Live. This system was compared against OpenAI models such as GPT-Live-1 and GPT Realtime 2.1, as well as ByteDance's Doubao SeedDuplex and two Qwen Audio 3.0 models. The publication on the OpenMOSS blog from November 13th outlines the areas where MOSS-Live excels and where it falls short. It should be noted that all presented figures are vendor data, and information regarding sample sizes, uncertainty estimates, and full testing conditions has not been disclosed.

MOSS-Live ranked first across all six stated full-duplex interaction metrics. The system responded to speech not addressed to it only 2% of the time, which is significantly better than 68% for GPT-Live-1 and 75% for Doubao SeedDuplex. Furthermore, it interrupted the user during pauses only 1.44% of the time, compared to 10.37% and 14.29% for its competitors. The system correctly ignored external interruptions in 68% of cases, whereas other models showed rates of 21% and 13%, and maintained its behavior during brief confirmations like 'mm-hmm' in 98.17% of instances.

Results on other parameters were mixed. Using the FDB v3 toolkit, MOSS-Live achieved 51% success, placing it on par with Doubao SeedDuplex as a leader and surpassing GPT-Live-1 with its 45%. However, the system's response time in tool-use scenarios, which was 2.36 seconds, was slower than 1.61 seconds for GPT Realtime 2.1. In the multi-turn task benchmark τ-Voice, MOSS-Live scored 57.93%, falling short of GPT-Live-1's 67.68%, but significantly outperforming Doubao with 17.38%. The percentage of times the system yielded the floor for two seconds was 52.49%, much lower than over 93% for the Qwen Audio models. Regarding audio understanding on Big-Bench Audio, MOSS-Live showed 88.40%, which was lower than Doubao's 90.50%. When following multi-turn instructions, the system received 3.35 out of 5 points, while GPT-Live-1 scored 3.72; however, MOSS-Live led in quality of responses after interruptions, reaching 4.88.

The MOSS-Live architecture combines a background model responsible for listening, queue management, and speech, with a background model responsible for reasoning, tool calling, and longer tasks. These two models exchange memory, context, and task state through a coordination layer, allowing the dialogue to continue while hotel searches or other operations are being performed. The system also supports streaming video, screen sharing, and real-time interpretation.

The system is available via an online sandbox and through the WebSocket realtime API under the model ID moss-live-1.0. MOSI Intelligence, located in the Shanghai Innovation Institute incubator, previously released the MOSS-Image and MOVA models jointly with the OpenMOSS team.
Similar stories

Tencent Hunyuan Hy Realtime Voice AI Model Can Independently Determine the Need for Search and Perform Songs Upon Request
Read more
pandaily.com

Tencent Hunyuan Hy Realtime Voice AI Model Can Independently Determine the Need for Search and Perform Songs Upon Request

Tencent Hunyuan has introduced the Hy Realtime model, a real-time voice model that integrates tool invocation and singing capabilities into everyday conversation. This model is already available in voice calls on the Tencent Yuanbao platform and in Tencent's customer support service. The company announced that Hy Realtime will soon be offered via API on Tencent Cloud. The model was unveiled on November 13th.

According to Tencent's statements, Hy Realtime was developed taking into account the characteristics of human speech. The model is capable of handling features such as mumbling, phrase interruptions, or self-correction during thought. The context of the surrounding conversation is used to reconstruct the true meaning. Furthermore, its capabilities for multi-turn instruction following and context management have been improved, allowing the model to track the user's intent throughout extended dialogues.

The model also possesses the function of invoking external tools. Based on the content of the conversation and the user's intentions, it decides whether a web search is necessary, then manages this search, executes the tool call, and provides a voice response within a single process. Regarding output quality, Tencent asserts that the model surpasses its predecessor in audio quality, pronunciation, prosody, and emotional expression, ensuring more natural tonal variations during the dialogue.

The singing functionality was developed in collaboration with the Tencent Music Entertainment AI team. Users can request compositions by specifying parameters such as artist, album, genre, language, release year, or popularity, and they can combine these conditions and refine their requests in subsequent turns. In an example from Tencent, a user requested an English folk song released between 2010 and 2020, and the model found a suitable option and sang it. Tencent notes that they tuned the vocals to provide expressiveness, natural phrasing, breathing, as well as melody and rhythm.

Tencent reports positive results from internal blind tests conducted by experts in search and answer tasks, as well as from an internal test set for the no-thought mode and several public voice benchmarks. The company characterizes its overall performance on these public tests as leading. It should be noted that these are the company's own evaluations, and the published text does not provide sample sizes or test configurations.

Users can test the model in the latest Yuanbao application by selecting the 'Chuyu' voice in voice calls, or through the Tencent Cloud web demo. Tencent plans further development in the direction of two-way interaction, long-term personalized memory, and coordination between the main conversational agent and background agents.

JBL SB180 Soundbar with Black Friday Discount on Mercado Livre
Read more
tecnoblog.net

JBL SB180 Soundbar with Black Friday Discount on Mercado Livre

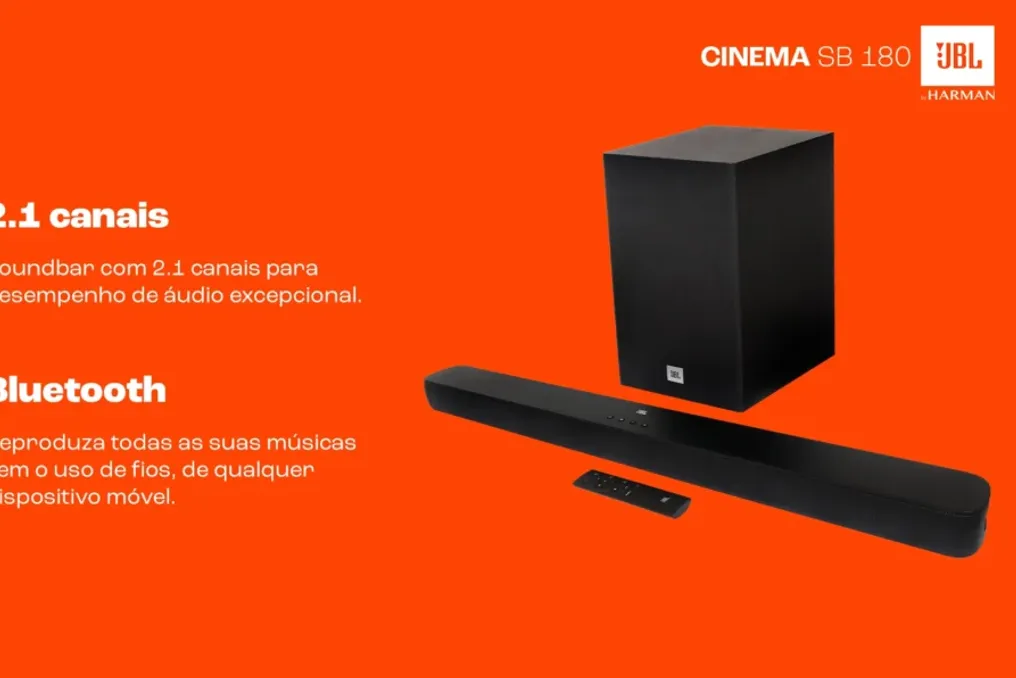
The JBL SB180 soundbar is available at a promotional price of R$ 778.04 via Pix, by applying the Black Friday 2026 coupon, which offers a discount of R$ 20 OFF. To take advantage of this offer, the coupon must be entered on the purchase page.

This audio peripheral, which includes a subwoofer, has a 47% reduction compared to its original price of R$ 1,469, and is available on Mercado Livre.

The JBL SB180 model is equipped with two integrated speakers, providing a total power of 110 W RMS. Additionally, it features a 60 W RMS wireless subwoofer, allowing it to be placed in strategic positions to ensure the sound fills the room, making it suitable for small to medium-sized living rooms.

In terms of connectivity, the peripheral has HDMI ARC, USB, and Bluetooth 5.3 inputs, allowing connection to televisions and various other electronic devices. For cinema enthusiasts, there is Cinema mode, designed to simulate the experience of a movie theater. Furthermore, Music and News modes are configured to adapt the content, whether it is music programs or news reports.

The dimensions of the soundbar are 9.2 cm wide by 6.3 cm high and 9.9 cm deep, weighing 2.1 kg. It also incorporates two 25W RMS racetrack drivers, a technology that ensures well-balanced frequency maintenance.

For those looking for a good cost-benefit option, the JBL SB180 can be purchased for R$ 778.04 via Pix, using the R$ 20 OFF Black Friday coupon on Mercado Livre. Tecnoblog's daily finds selects the best electronics promotions based on historical price data.

Live streams boost sales during Double 11 sale in Brazil
Read more
cgtn.com

Live streams boost sales during Double 11 sale in Brazil

The Double 11 sale, which the company Alibaba developed in China to celebrate Singles' Day, will take place this Wednesday. In Brazil, this event opens the largest two-week shopping period of the year, with more and more sales occurring in real-time via video connection.

Paulo Cabral from CGTN reports on this situation from São Paulo.

Popular