SenseTime releases artificial intelligence model with 9 billion parameters using layer reuse for deep processing
Read more
TechNode
technode.com

SenseTime releases artificial intelligence model with 9 billion parameters using layer reuse for deep processing

SenseTime has introduced SenseNova Loop-9B-Preview, a multimodal model available in the open source. This model utilizes a recomputation method to increase processing depth without needing to duplicate the corresponding model weights. The announcement of this release was made on October 30th.

The model is capable of accepting both text and image data as input, generating text to perform tasks related to document understanding, code writing, and external tool usage.

It functions by running the common block of 24 decoder layers twice, which allows for the creation of a deeper computational path based on a base model with approximately nine billion parameters.

The documentation training configuration supports sequences up to 262,144 tokens and integrates examples including text, images, code, and tool usage. SenseTime has published the model weights, inference instructions, and a training guide, distributing the project under the Apache 2.0 license.

Similar stories

MemTensor releases open-source MemT 1.0 model with memory for preserving long histories
Read more
pandaily.com

MemTensor releases open-source MemT 1.0 model with memory for preserving long histories

The Chinese company MemTensor has introduced and made publicly available a series of models it calls memory-oriented foundation models, named MemT 1.0. This series includes two models: MemT-1.0-Flash, which has a total of 288 billion parameters, of which 17 billion are actively used, and MemT-1.0-Nano, which has 36 billion total parameters and 3 billion active ones.

The weights of these models are available on the Hugging Face platform, and the corresponding code is hosted on GitHub along with a technical report.

The models are designed to solve a common problem associated with long dialogues. Most existing systems store the entire history in the context window, which leads to slowdowns and increased inference costs with every new turn. Instead, MemT integrates a trainable memory module directly into the model.

After each interaction, the model records new information into a fixed memory state and retrieves it when necessary, instead of re-reading the entire previous log every time.

MemTensor reports that the training of the models was conducted in two stages based on 34 billion tokens: first, the model learned to write information into memory, and then it learned to answer questions using this stored information.

Performance Results and Comparison

All presented performance metrics are based on the company's own evaluation. MemTensor claims that end-to-end inference runs approximately 1.86 times faster than the full context approach with a history of 128 thousand tokens, and about 3.99 times faster with 256 thousand tokens.

The time to the first token response is estimated at approximately 104–112 milliseconds for the memory model, compared to approximately 445 milliseconds for full context at 256K. Furthermore, the company notes that the memory state size per session with a 256K history is about 40 MB, which is significantly less than the 5.06 GB required for the full context cache, representing a reduction of approximately 130 times.

On 11 memory benchmarks, MemTensor reports average scores of 50.6 for Flash and 47.0 for Nano. These results place the models first and second among comparable parametric memory methods and roughly match the results of retrieval-augmented approaches on average, even without retrieving history during the query.

The company also emphasizes that adding memory did not degrade the overall capabilities of the Flash model under tests with a high number of distractors.

Developers should note the licensing terms: the repository code is published under the non-commercial PolyForm license, while the model weights have Apache and MIT licenses, respectively.

The team plans further development towards improving long-term memory, increasing memory capacity, and reducing memory update costs, with the long-term goal of creating agents that continue to learn based on their interactions.

DeepSeek releases DeepInfer code to accelerate and optimize AI model execution
Read more
olhardigital.com.br

DeepSeek releases DeepInfer code to accelerate and optimize AI model execution

Last Tuesday (20), DeepSeek made the code for DeepInfer public, a software designed to operate its artificial intelligence (AI) models. This tool was created with the goal of improving processing efficiency and reducing the time required to generate responses.

With the release of the code, developers and corporations have the opportunity to analyze the program's operation and adapt it to various projects, provided they meet the technical requirements and established terms of use. According to DeepSeek itself, this action aims to decrease energy and computational resource consumption, making AI model operation more efficient. However, practical results will depend on usage conditions and available infrastructure.

Currently, DeepInfer is specifically compatible with the DeepSeek-V4.1-Flash model. Although opening the code allows other developers to investigate and use the technology, it is important to note that not the entire company execution system has been made public, as some infrastructure components remain closed.

During his participation in the Olhar Digital News program, physicist Roberto 'Pena' Spinelli, a Machine Learning specialist, commented on this news. The researcher clarified the distinction between providing an AI model and releasing the software responsible for executing it. To explain this difference, he used the analogy of a car.

Pena detailed that simply sharing the model is not equivalent to providing all the necessary tools to operate it effectively. While the model carries the parameters that guide response generation, the inference software groups the mechanisms that enable its functioning. The opening of this code can assist developers who intend to implement their own solutions.

The specialist compared the situation by saying: 'Before, they only shared the engine blueprint, which is the artificial intelligence itself. What they are doing now is delivering the functioning of the entire car. All the software and the mechanism of how they execute the artificial intelligence have been released to the public.'

This comparison helps to understand the difference between the two elements, but there is a caveat: the availability of DeepInfer does not imply that all elements of DeepSeek's infrastructure are accessible. Nevertheless, access to the code allows programmers and researchers to study the execution methodologies employed by the company and evaluate how to apply them in other works.

The initiative may also benefit DeepSeek's commercial strategy. By sharing part of its technology, the company opens avenues for other developers to use it, contribute improvements, and create compatible applications. This adoption can expand the reach of its technology in a highly competitive market, where several companies compete to offer more accessible and efficient models.

Pena added: 'DeepSeek wants to create an ecosystem so that more people and companies start using its products.' He continued: 'By showing how to assemble the complete structure, it encourages the public to abandon more expensive paid platforms. It is a consistent way to assert itself in an extremely contested sector.'

The release of DeepInfer underscores that competition in the field of AI is not limited only to the ability of models to generate responses, but also to the efficiency required to execute them. By sharing part of its technology, DeepSeek increases the options for software use and strengthens its position in the sector. The impact of this measure will depend, among other factors, on the performance achieved in various environments and the adoption by developers and companies.
VAST releases open-source model EdenLive for rendering simple game frames into detailed video
Read more
pandaily.com

VAST releases open-source model EdenLive for rendering simple game frames into detailed video

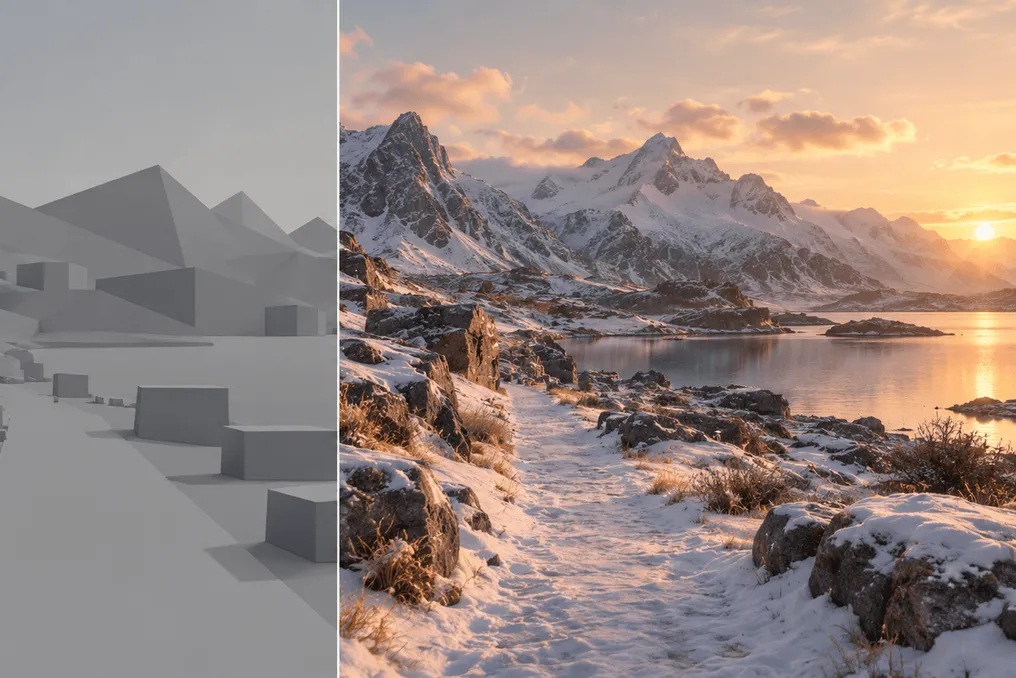
VAST, a company specializing in generative AI in 3D and behind the Tripo platform, has made the EdenLive model publicly available. This model operates in real-time and is capable of taking simplified game frames or existing video, continuously re-rendering them into detailed images in a chosen style, which can range from photorealistic to anime.

The release includes 5B and 14B model weights, code for real-time inference, a technical report, and end-to-end usage demonstrations. It is important to note that EdenLive does not simulate the world on its own; instead, a higher-level program, such as a game engine or code written by a coding agent, is responsible for enforcing rules, tracking world state, and outputting a rough reference video.

After receiving this reference video, EdenLive performs the rendering, guided by the initial frame and a text prompt. VAST asserts that this separation allows game logic to remain explicit and testable, while concentrating the model's limited real-time capabilities solely on the visual appearance.

The approach was first presented in June as part of a larger world research effort known as Project Eden. According to VAST, the 5B model can operate at a frame rate above 24 frames per second at 720p resolution on a single Nvidia RTX 5090 GPU. The README file on GitHub specifies this figure as approximately 24.7 FPS at a resolution of 1280 by 704 pixels, utilizing acceleration from the LightX2V inference framework.

The technical report reports a rate of 29.8 FPS at the same resolution on a single H100, as well as 26.8 FPS at a resolution of 832 by 480 for the 14B model running on eight H100s. VAST states that the total latency from user input to the corresponding frame is in the hundreds of milliseconds, and the system can generate content continuously for several minutes.

Both models are based on the Wan2.2-TI2V-5B and Wan2.1-I2V-14B video models. The inference code and core diffusion, VAE, and decoder weights are distributed under the Apache 2.0 license, although not all components have this license. The visual encoder uses the DINOv3 license, and the image model used in the request-to-game workspace is under the Non-Commercial FLUX License, which restricts the use of this workspace to non-commercial purposes.

VAST also introduced Game Prototype Turbo—a skill that transforms a text prompt into a rough playable game, which EdenLive can then render. VAST demonstrations include a platformer where a character freezes lava to create waypoints, a two-player fighting game where health bars and round timers are tracked by a higher-level system, and video rendering that transforms a person filmed against a blue background into a cartoon character. Furthermore, the model demonstrates replacing human hands with robotic ones in first-person footage to create additional training data for embodied AI.

VAST notes that EdenLive is currently best suited for low-frequency interactions, such as scene inspection and box-pushing puzzles. Fast, intense gameplay, maintaining multi-character consistency, fine control over small objects, and visual stability during long sessions still require refinement.

Popular