ACE Robotics and NTU release open-source multi-modal world model Puffin-World
Read more
Pandaily
pandaily.com

ACE Robotics and NTU release open-source multi-modal world model Puffin-World

ACE Robotics, in collaboration with S-Lab from Nanyang Technological University, and with participation from Beijing Jiaotong University and the University of Michigan, has made Puffin-World publicly available. This unified multimodal world model considers physics, geometry, and appearance as integral three-dimensional states of the world.

The released package includes the code, models, and dataset Puffin-16M. The goal of this development is to enable perception and simulation ready for robots, rather than just predicting the next frame based on RGB images.

Most generative world models focus on predicting future pixels. However, Puffin-World integrates modeling of a gravity-aware physical state, which includes latitude indicators, depth-recovered geometry state, and an appearance state represented in RGB format. All these elements are linked through an Omni-Camera representation that combines absolute and relative camera frames.

Absolute landmarks anchor observations relative to real gravity and orientation, while relative ray geometry supports continuous viewpoint changes and composite motions. The model can estimate absolute roll, pitch, and vertical field of view from a single image, and also synthesize trajectories from arbitrary viewpoints, reconstruct dense geometry, and perform closed-loop exploration by correcting drift using gravity and position during camera movement in the generated scene, utilizing textual or visual data.

The training scale is provided by the Puffin-16M dataset, which contains approximately 15 million 'vision-language-camera' triplets in Puffin-Cam-15M and 1 million complex trajectories in Puffin-Traj-1M. These trajectories cover pitch, yaw, roll, and composite motions across various environments: indoor, outdoor, synthetic, and road scenes.

The team also used Puffin-World to add absolute camera pose labels to 28 public datasets covering about 44.5 million images, available for further research. This data contribution aims to fill the gap in absolute pose present in camera corpora based only on relative data, as they cannot train gravity alignment.

On four public camera-to-world benchmarks—Stanford2D3D, MegaDepth, TartanAir, and LaMAR—Puffin-World demonstrates state-of-the-art median errors. On Stanford2D3D, median errors for roll, pitch, and vertical field of view decrease to 0.29°, 0.53°, and 1.62°, respectively. Furthermore, the model shows the least roll within one degree on MegaDepth (0.28°), TartanAir (0.31°), and LaMAR (0.26°).

Design materials also indicate leading PSNR and LPIPS scores in multi-view rendering for RealEstate10K and low angular errors on test benches for arbitrary viewpoint camera control. The architecture combines a vision encoder aligned with geometry, a language model, a diffusion generator, and a lightweight connector. This allows understanding, generation, and reconstruction to utilize a unified structure without task-specific external geometry modules.

For embodied intelligence systems (embodied stacks), the open release provides a single control point capable of perceiving absolute camera physics, simulating controlled viewpoints, and recreating coherent three-dimensional worlds. This represents a shift from simple frame prediction to modeling how a physical scene exists and how it can be explored.
Similar stories

ACE Robotics introduces ACE-CaP-0: AI agents write reusable code for robots with 92.1% success rate
Read more
pandaily.com

ACE Robotics introduces ACE-CaP-0: AI agents write reusable code for robots with 92.1% success rate

ACE Robotics, a company focused on embodied artificial intelligence and led by co-founder SenseTime's Yang Xiaogang, has released the ACE-CaP-0 model. As part of this research approach, a general AI agent is responsible for writing, testing, and refining robot control software, which is then fixed as reusable skills that can operate autonomously without agent intervention.

The paper was posted on arXiv on November 12, and the company announced the work on November 13. This method is based on the 'Code as Policies' concept, which describes robot behavior through executable code instead of calling a large model at every step. The authors argue that multiple model calls slow down the robot, whereas the finished program utilizes the logic already embedded during its creation.

The main challenge lies in developing reliable code without requiring numerous expensive physical tests. In ACE-CaP-0, the agent independently decides when to request assistance.

Methodology and Results

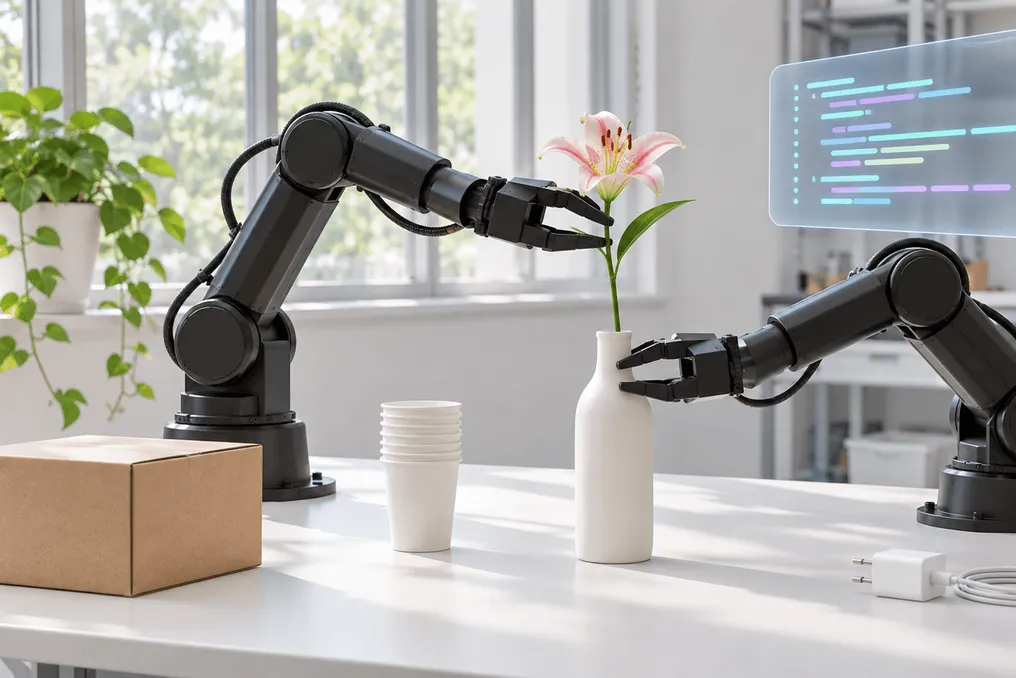
In the comparison conducted by the team, the best results were achieved using on-demand demonstrations combined with selective simulation usage. The success metrics were obtained through the authors' own tests. Across eight real-world tasks, including charging station installation, bread packaging, bottle cap removal, cup insertion, flower placement, and shoe packaging, the recorded programs successfully completed 221 out of 240 attempts, achieving 92.1% success.

Seven of these tasks reached a success rate of at least 90%, and the charging station installation task demonstrated 100% success. The average task completion time ranged from 0.97 to 2.27 minutes. The programs function based on the robot's own perception and control, without human or coding agent intervention.

It should be noted that the results obtained are based on one setup with two manipulators selected by the team and have not yet been independently reproduced. ACE Robotics states that this work aligns with their plan to integrate general models with their global Kairos model.

ACE Robotics uses Mundo model and self-improving skills to automate hotel laundry process
Read more
pandaily.com

ACE Robotics uses Mundo model and self-improving skills to automate hotel laundry process

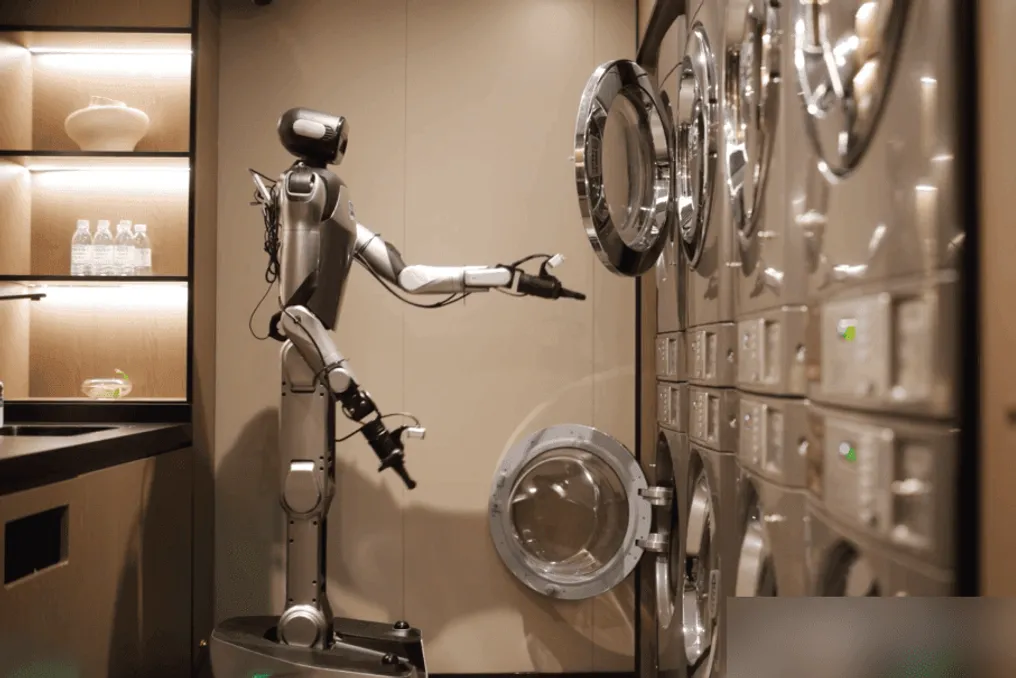
ACE Robotics has implemented its Mundo model to perform tasks in a hotel laundry. As part of this workflow, the robot collects linen baskets from guest rooms, delivers them to the laundry, starts washing and drying machines, and then returns the clean clothes.

The company describes this system as a collaboration between two 'brains' combined with a self-improvement cycle. This is the first commercial use of the Mundo model since ACE Robotics and S-Lab from NTU presented it last month.

The Mundo model transforms photographs of hotel rooms, corridors, and the laundry itself into a digital twin that robots can physically interact with. This digital twin includes characteristics such as object mass and coefficient of friction. Each attempt in this virtual environment generates trajectories, contact states, and visual feedback, which are used to refine the robot's policies before operating on the real object.

The work is divided between two components. A general cloud model, identified by QbitAI as GPT-Astra, is responsible for task decomposition, reasoning, and strategy search within Mundo. Once a method reaches convergence, it is saved as a reusable skill. Then, a local execution model on the robot calls these skills to perform precise actions.

ACE Robotics notes that using the cloud model for every real-time decision took over thirty minutes for a full cycle, whereas the local model completed the same cycle in only 18.648 seconds. A scheduler called BotAgent breaks down the washing process into 53 atomic actions and 14 semantic steps, organizing over 200 sequences of actions depending on room location, elevator status, and laundry machine queues.

When any skill fails, the cloud model analyzes video from multiple cameras and sensor logs to determine the cause of the problem. In one instance, it switched to an overhead camera when the wrist camera was blocked. In another case, it adjusted the gripper lift trajectories and finger angles when jeans got stuck in the dryer drum. The robot is also capable of resetting the scene autonomously, and a separate copy of the model evaluates each round, allowing for the rollback of worse versions.

For just unloading the dryer, ACE Robotics conducted 165 cycles on real robots over 57 hours, resulting in 37 improvement suggestions and about 80 skill versions. The cycle time stabilized at 170–210 seconds, and the percentage of jeans left in the drum decreased from an average of 48% to 32%, with the best result being 19%. Chairman Wang Xiaogan stated that instant retail is the likely next scenario. It should be noted that these results were achieved by the company and have not yet undergone independent verification.

Noitom Robotics releases HiPHI-Hand dataset used to train NVIDIA's EgoHand model
Read more
pandaily.com

Noitom Robotics releases HiPHI-Hand dataset used to train NVIDIA's EgoHand model

Noitom Robotics, a company specializing in data for physical artificial intelligence, has released the HiPHI-Hand dataset on the Hugging Face platform. This dataset consists of hand movement recordings which, according to the company, were used to train NVIDIA's EgoHand model.

The announcement of the release was made at the CoRL 2026 robotics conference held in Austin, Texas, while the actual release on Hugging Face is dated November 9th.

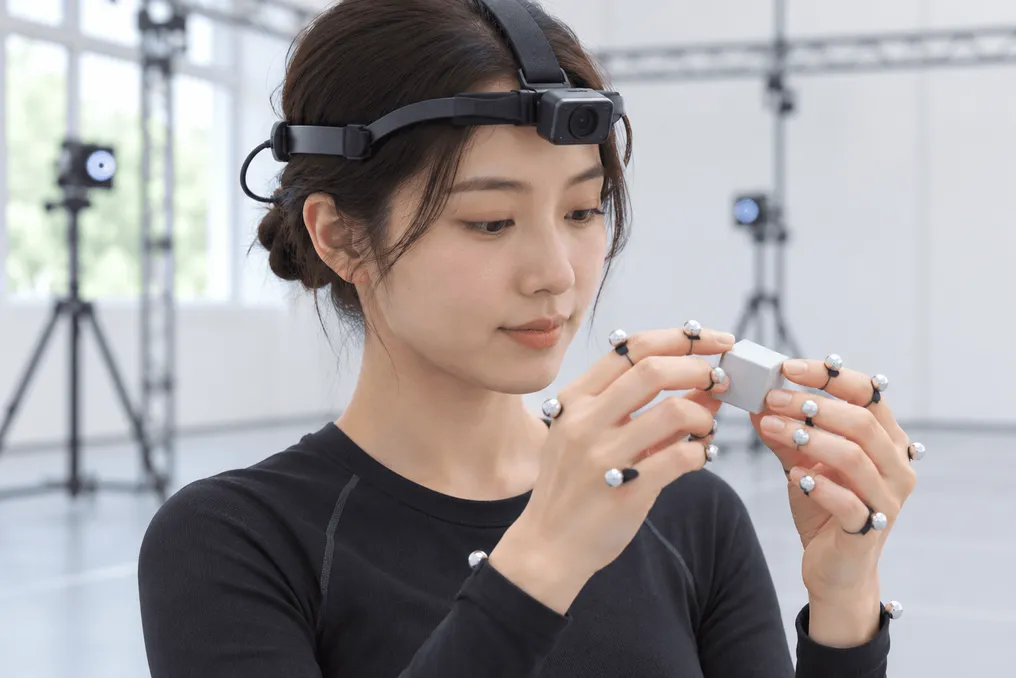
Noitom specified that the presented data is the exact recording that was provided to NVIDIA. It includes 11 hours of first-person synchronized video captured using the SOL headset, accounting for the camera extrinsic relative to the headset's inertial sensor, as well as three-dimensional coordinates of the wrist joints obtained through optical motion capture. To ensure sub-millimeter accuracy, even when hands are obscured from the camera, micro-markers were placed on the fingers.

The Hugging Face page contains five subsets, which collectively comprise 794 clips of stereo video with a resolution of 1360 by 1360 pixels, recorded at 30 frames per second. This data is accompanied by annotations in two skeletal schemas: 21 MediaPipe joints and 25 Vicon joints for each hand, with a total file size of 69.5 GB.

The EgoHand model, developed based on NVIDIA Isaac Capture, is capable of reconstructing the three-dimensional pose and shape of the hand from a single first-person video. NVIDIA distributed this model under the OpenMDW license, which permits its free commercial use. According to Noitom's data on NVIDIA's metrics, the model was trained on 14 million images derived from synthetic data, real video recordings, and multi-camera motion capture, demonstrating state-of-the-art zero-shot accuracy on public egocentric benchmarks and operating in approximately 9 milliseconds per frame.

NVIDIA converted Noitom's recordings into its SOMA-Hand representation as one of several real-world sources, meaning HiPHI-Hand is not a complete training set for EgoHand. It is important to note that the licensing of the dataset differs from the licensing of the model itself. HiPHI-Hand uses the ModalityNet Open Research License v1.0, which is free for non-commercial research, education, and evaluation; commercial use requires a separate license from Noitom, and users must request access via the Hugging Face page. This dataset follows HiPHI, another Noitom dataset on object and full-body interaction, which was released on Hugging Face in August.

At Noitom's booth at the CoRL conference, visitors could try on the SOL headset and observe how their hands were reconstructed in 3D in real time using EgoHand. The company also integrated EgoHand into one of its proprietary egocentric vision data pipelines, where it is used during the hand annotation stage.

The accuracy and speed mentioned in the article are data provided by NVIDIA to Noitom, and there is no independent benchmark that isolates the contribution of HiPHI-Hand to these metrics.

Popular